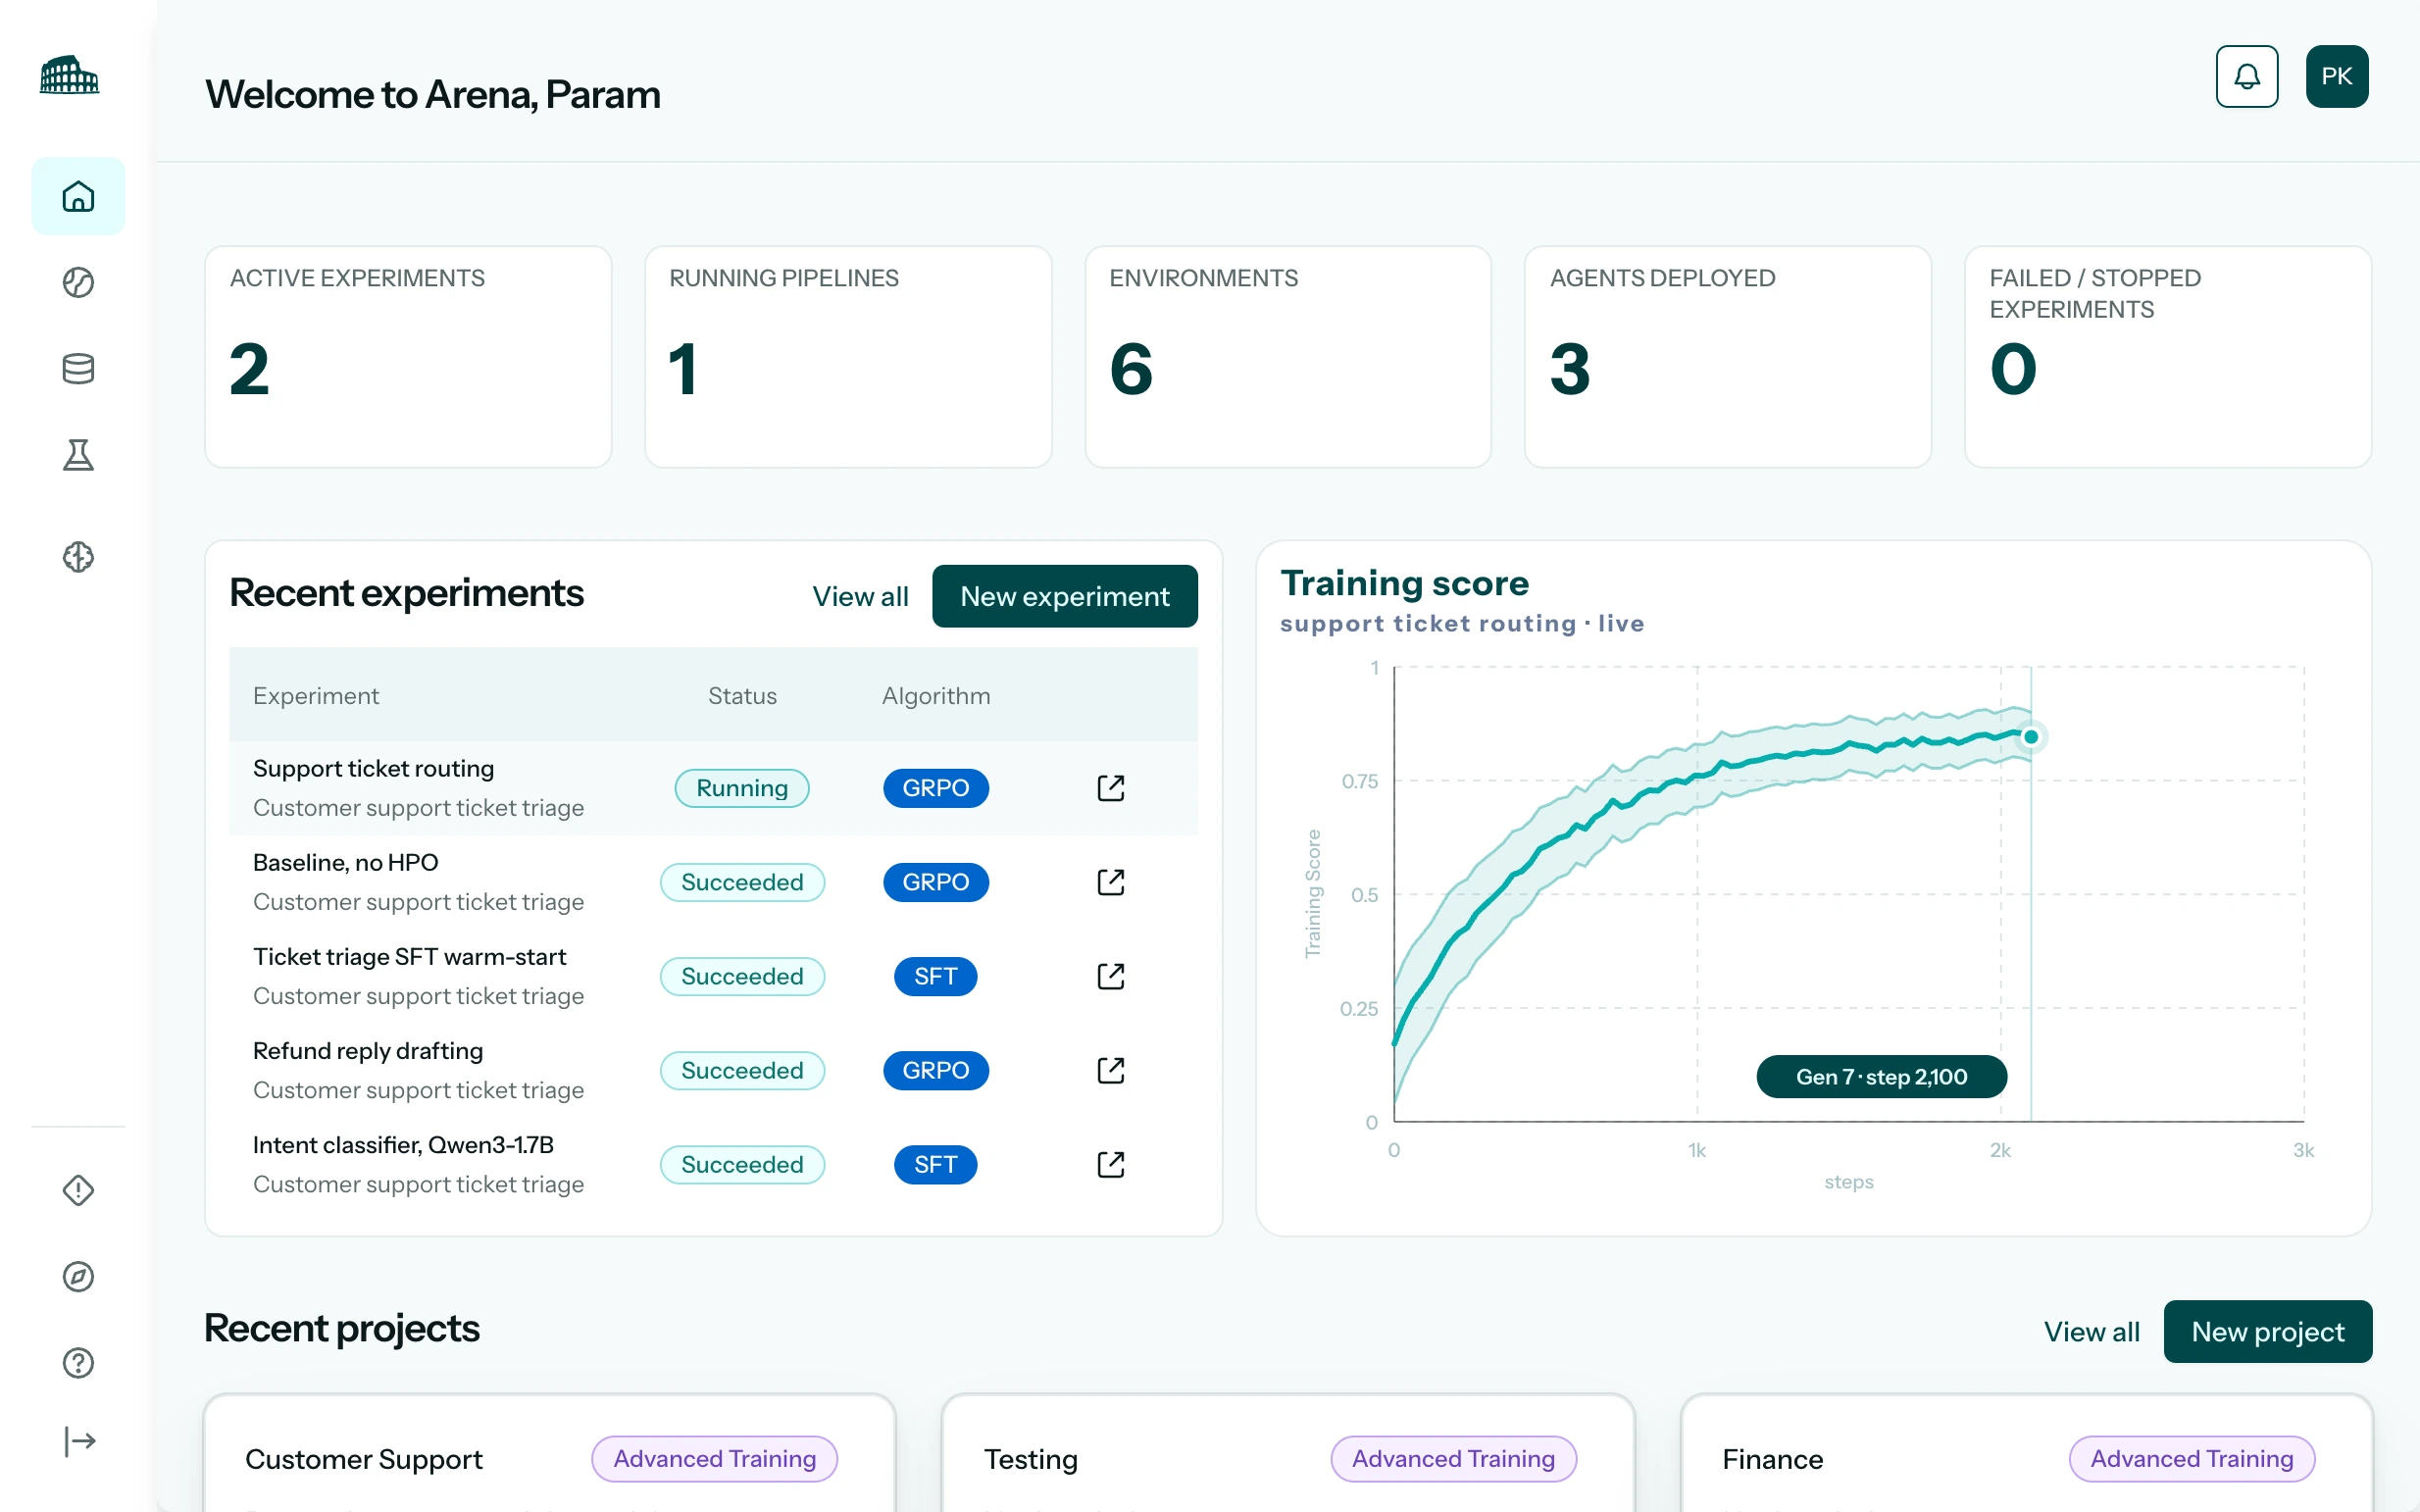
01Connect & validate
Bring your data.
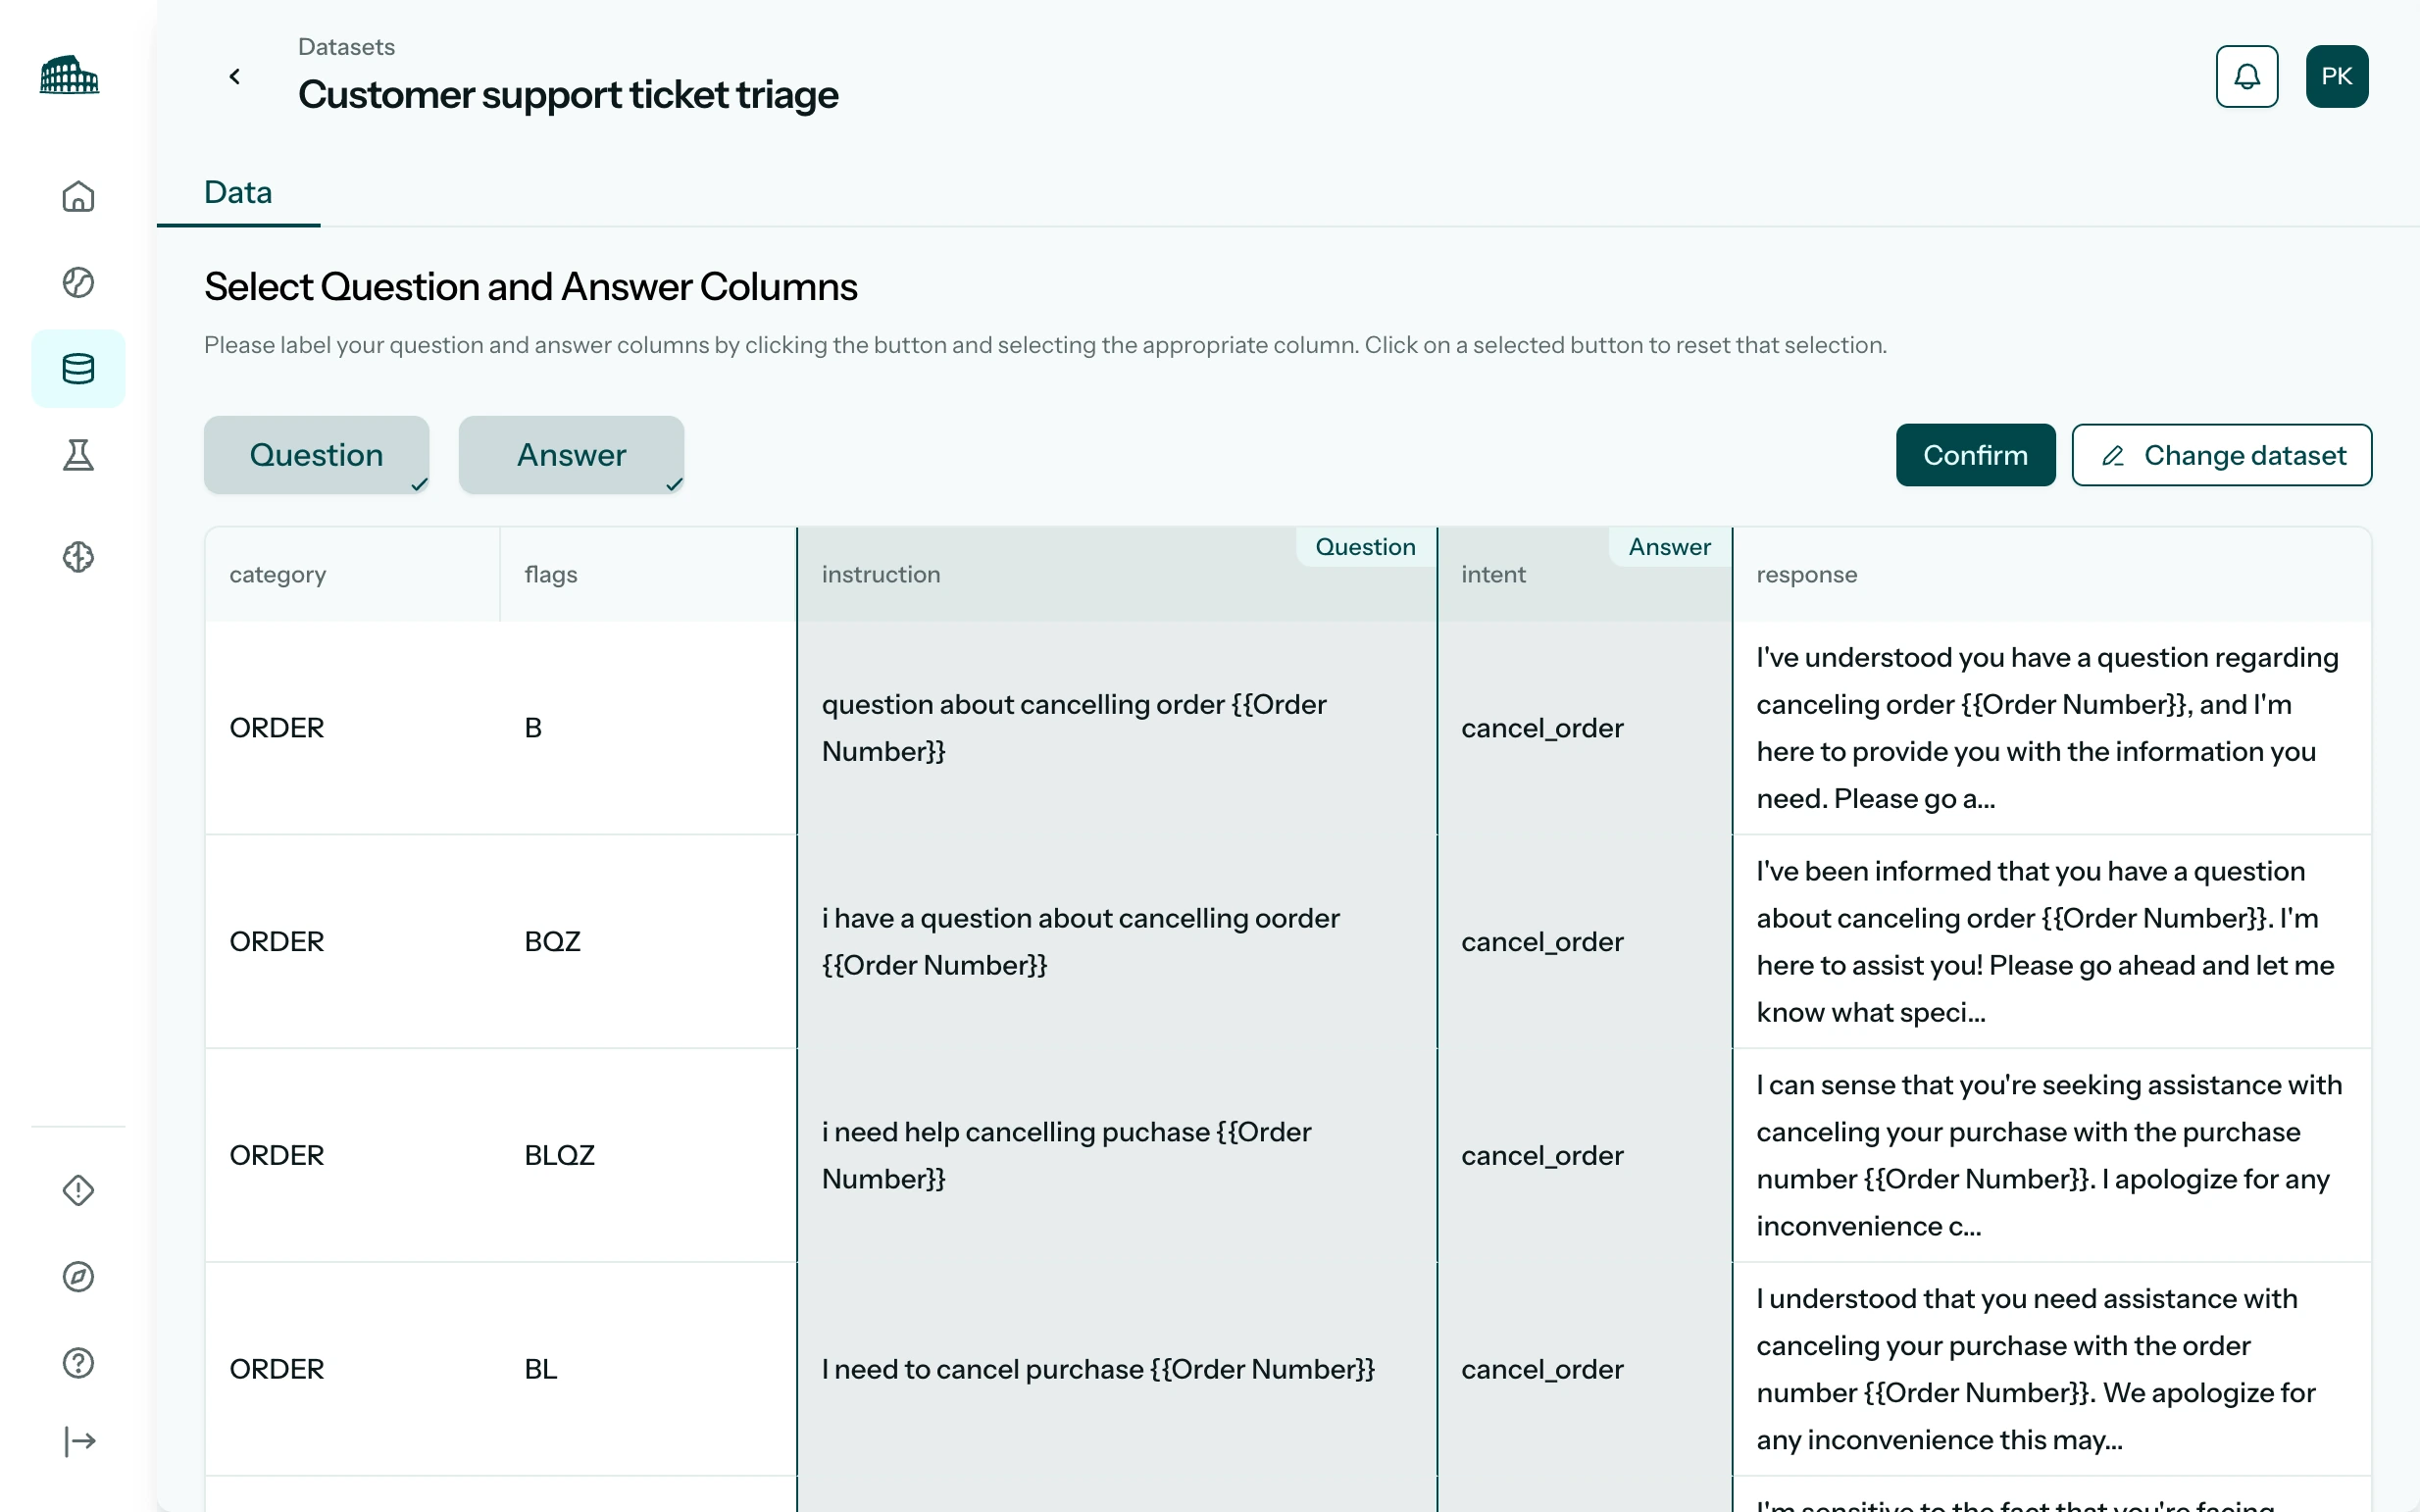
- Use Arena to prepare it as LLM datasets and RL environments.
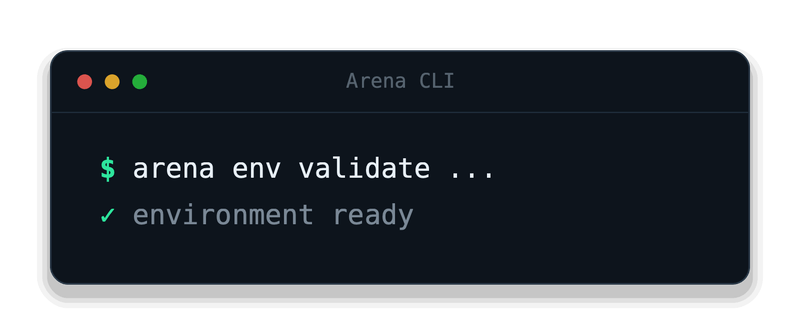
- Validate everything with feedback before training begins.
> arena: post-training for open models
Arena turns your raw data into agents, specialized at your task. Skip the reliance on someone else's frontier model.
Trusted by teams at


 RTDynamics
> now open: arena credits program
Fine-tune an open model or train an agent with reinforcement learning on your own data, then compare it with what you use today. We review every application and places are limited.
$20,000
Training and inference credits
30 days
To run your experiments
1:1 help
From our team to set up and measure your task
> blog
Read →
Read →
Nemotron 3.5 Super VL
Read →
$ pip install agilerl
Read →
> platform
Turn your workflows into training environments and let agents learn them directly.
Our evolutionary hyperparameter optimization and async-RL engine trains your agents 10x faster.
Reinforcement fine-tuning for LLM agents, with distributed training and one-click deployment.
Check your dataset or environment upfront and start training with full confidence.
> how it works
01Connect & validate
02Ready for launch
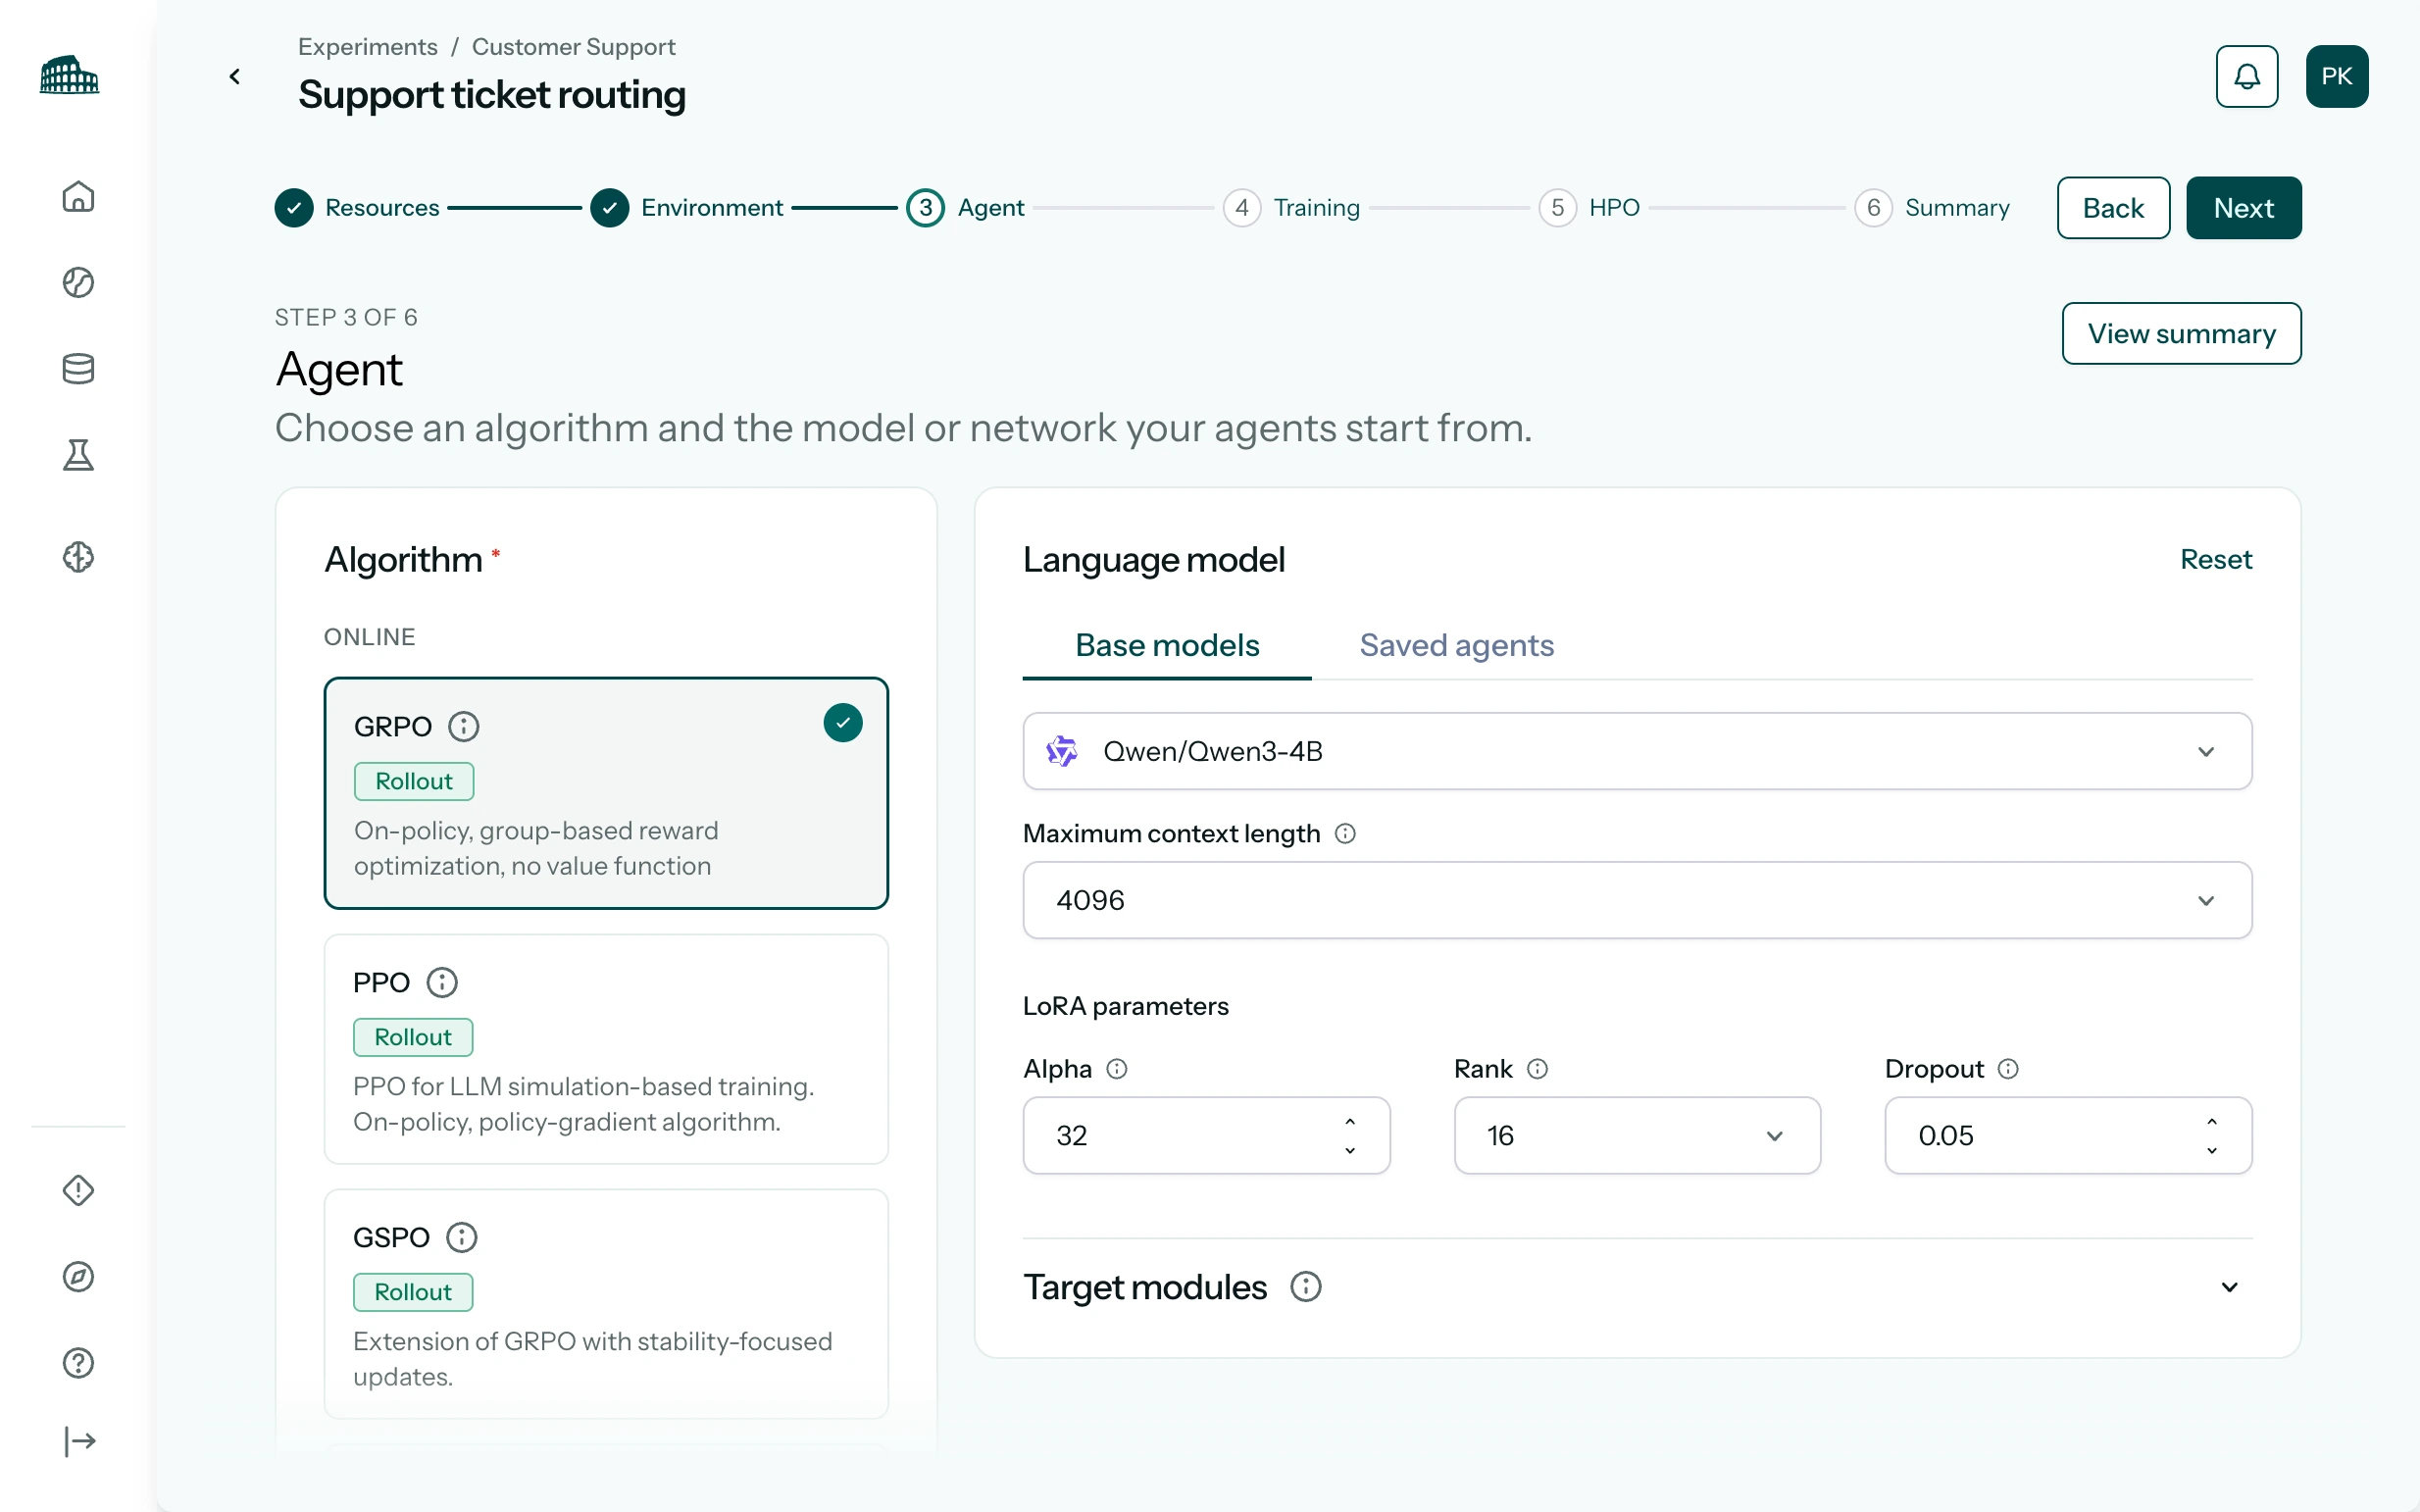
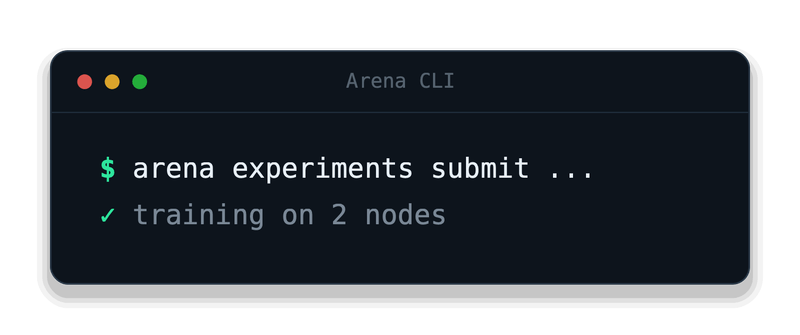
03Built for scale
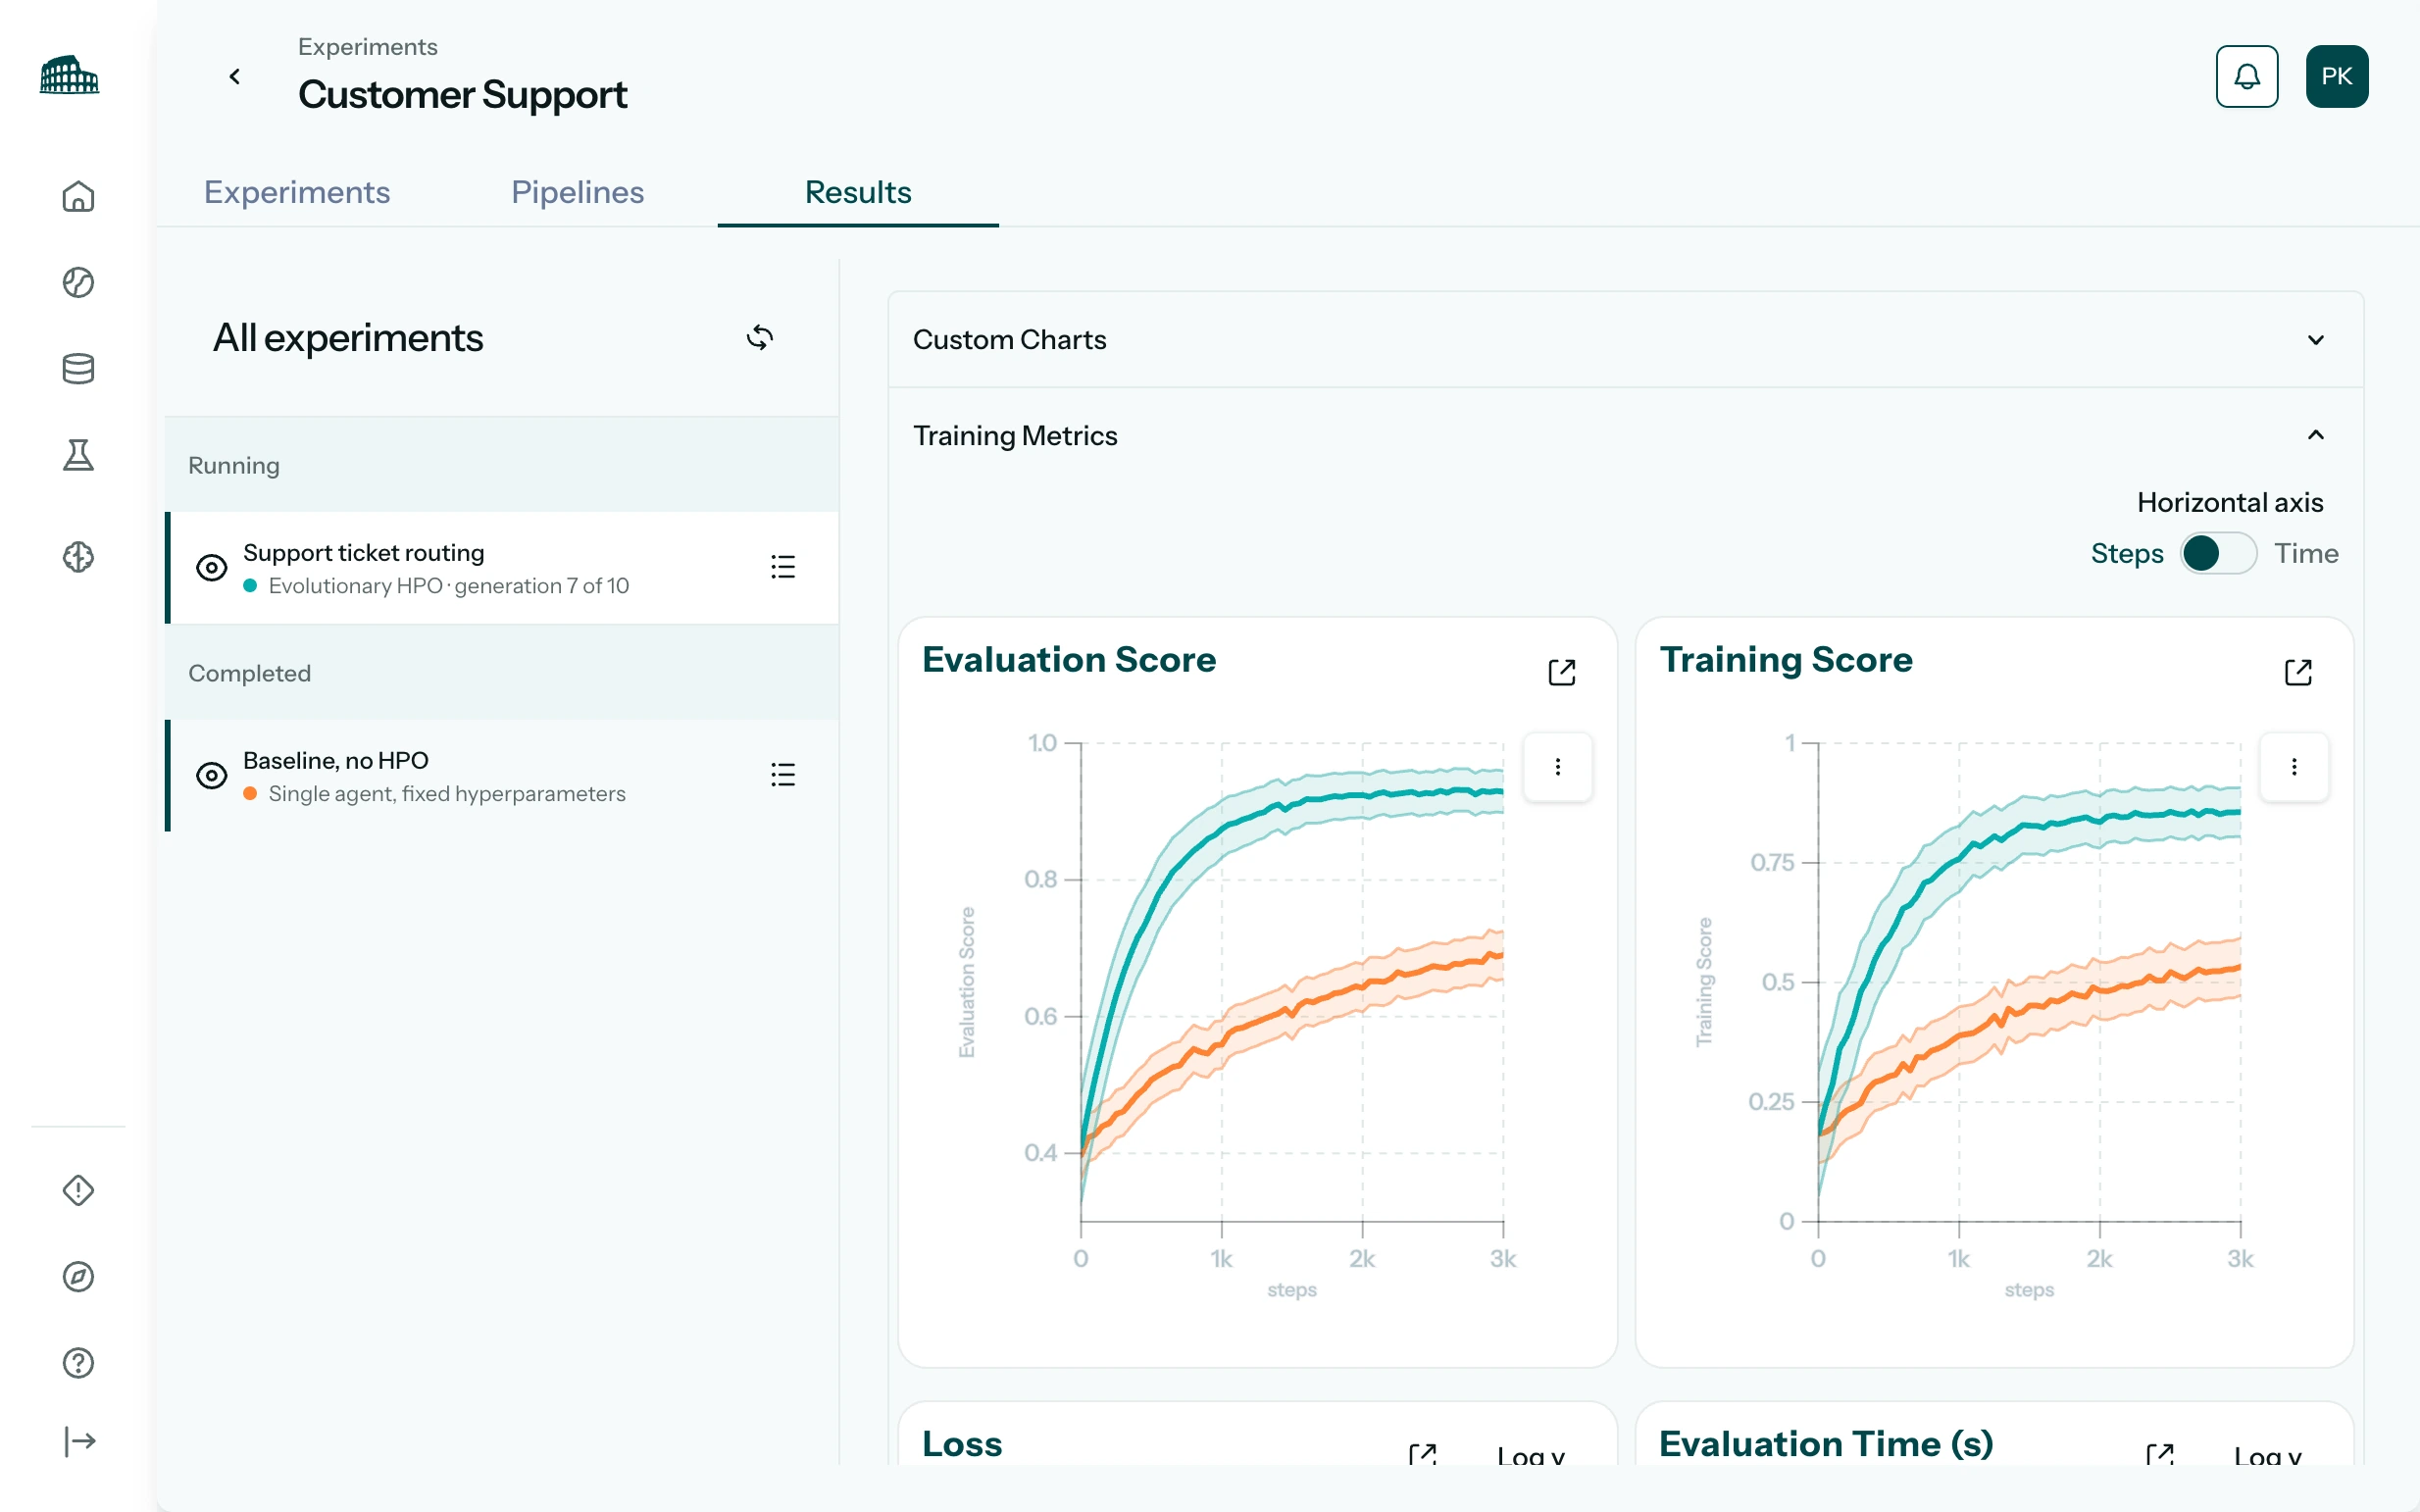
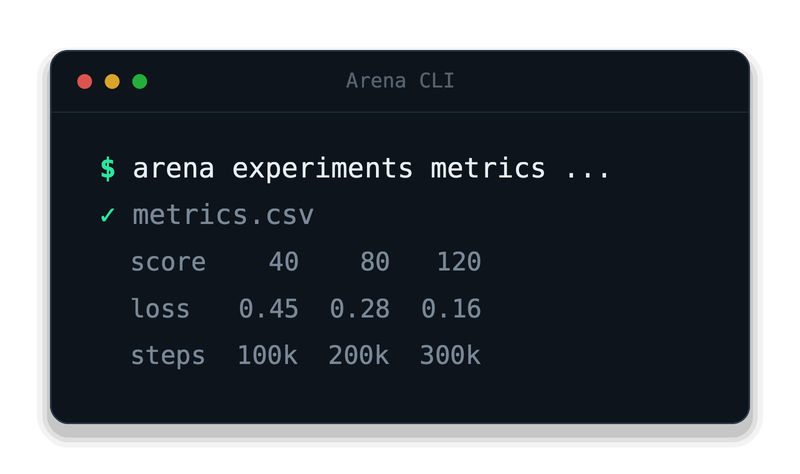
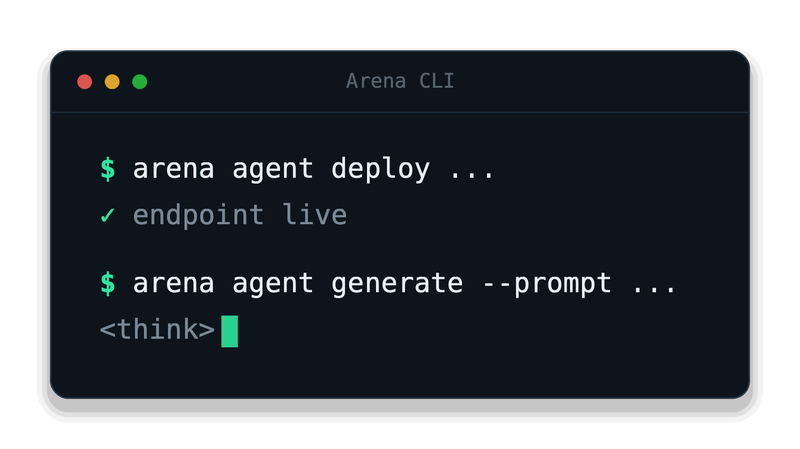
04Deploy & improve
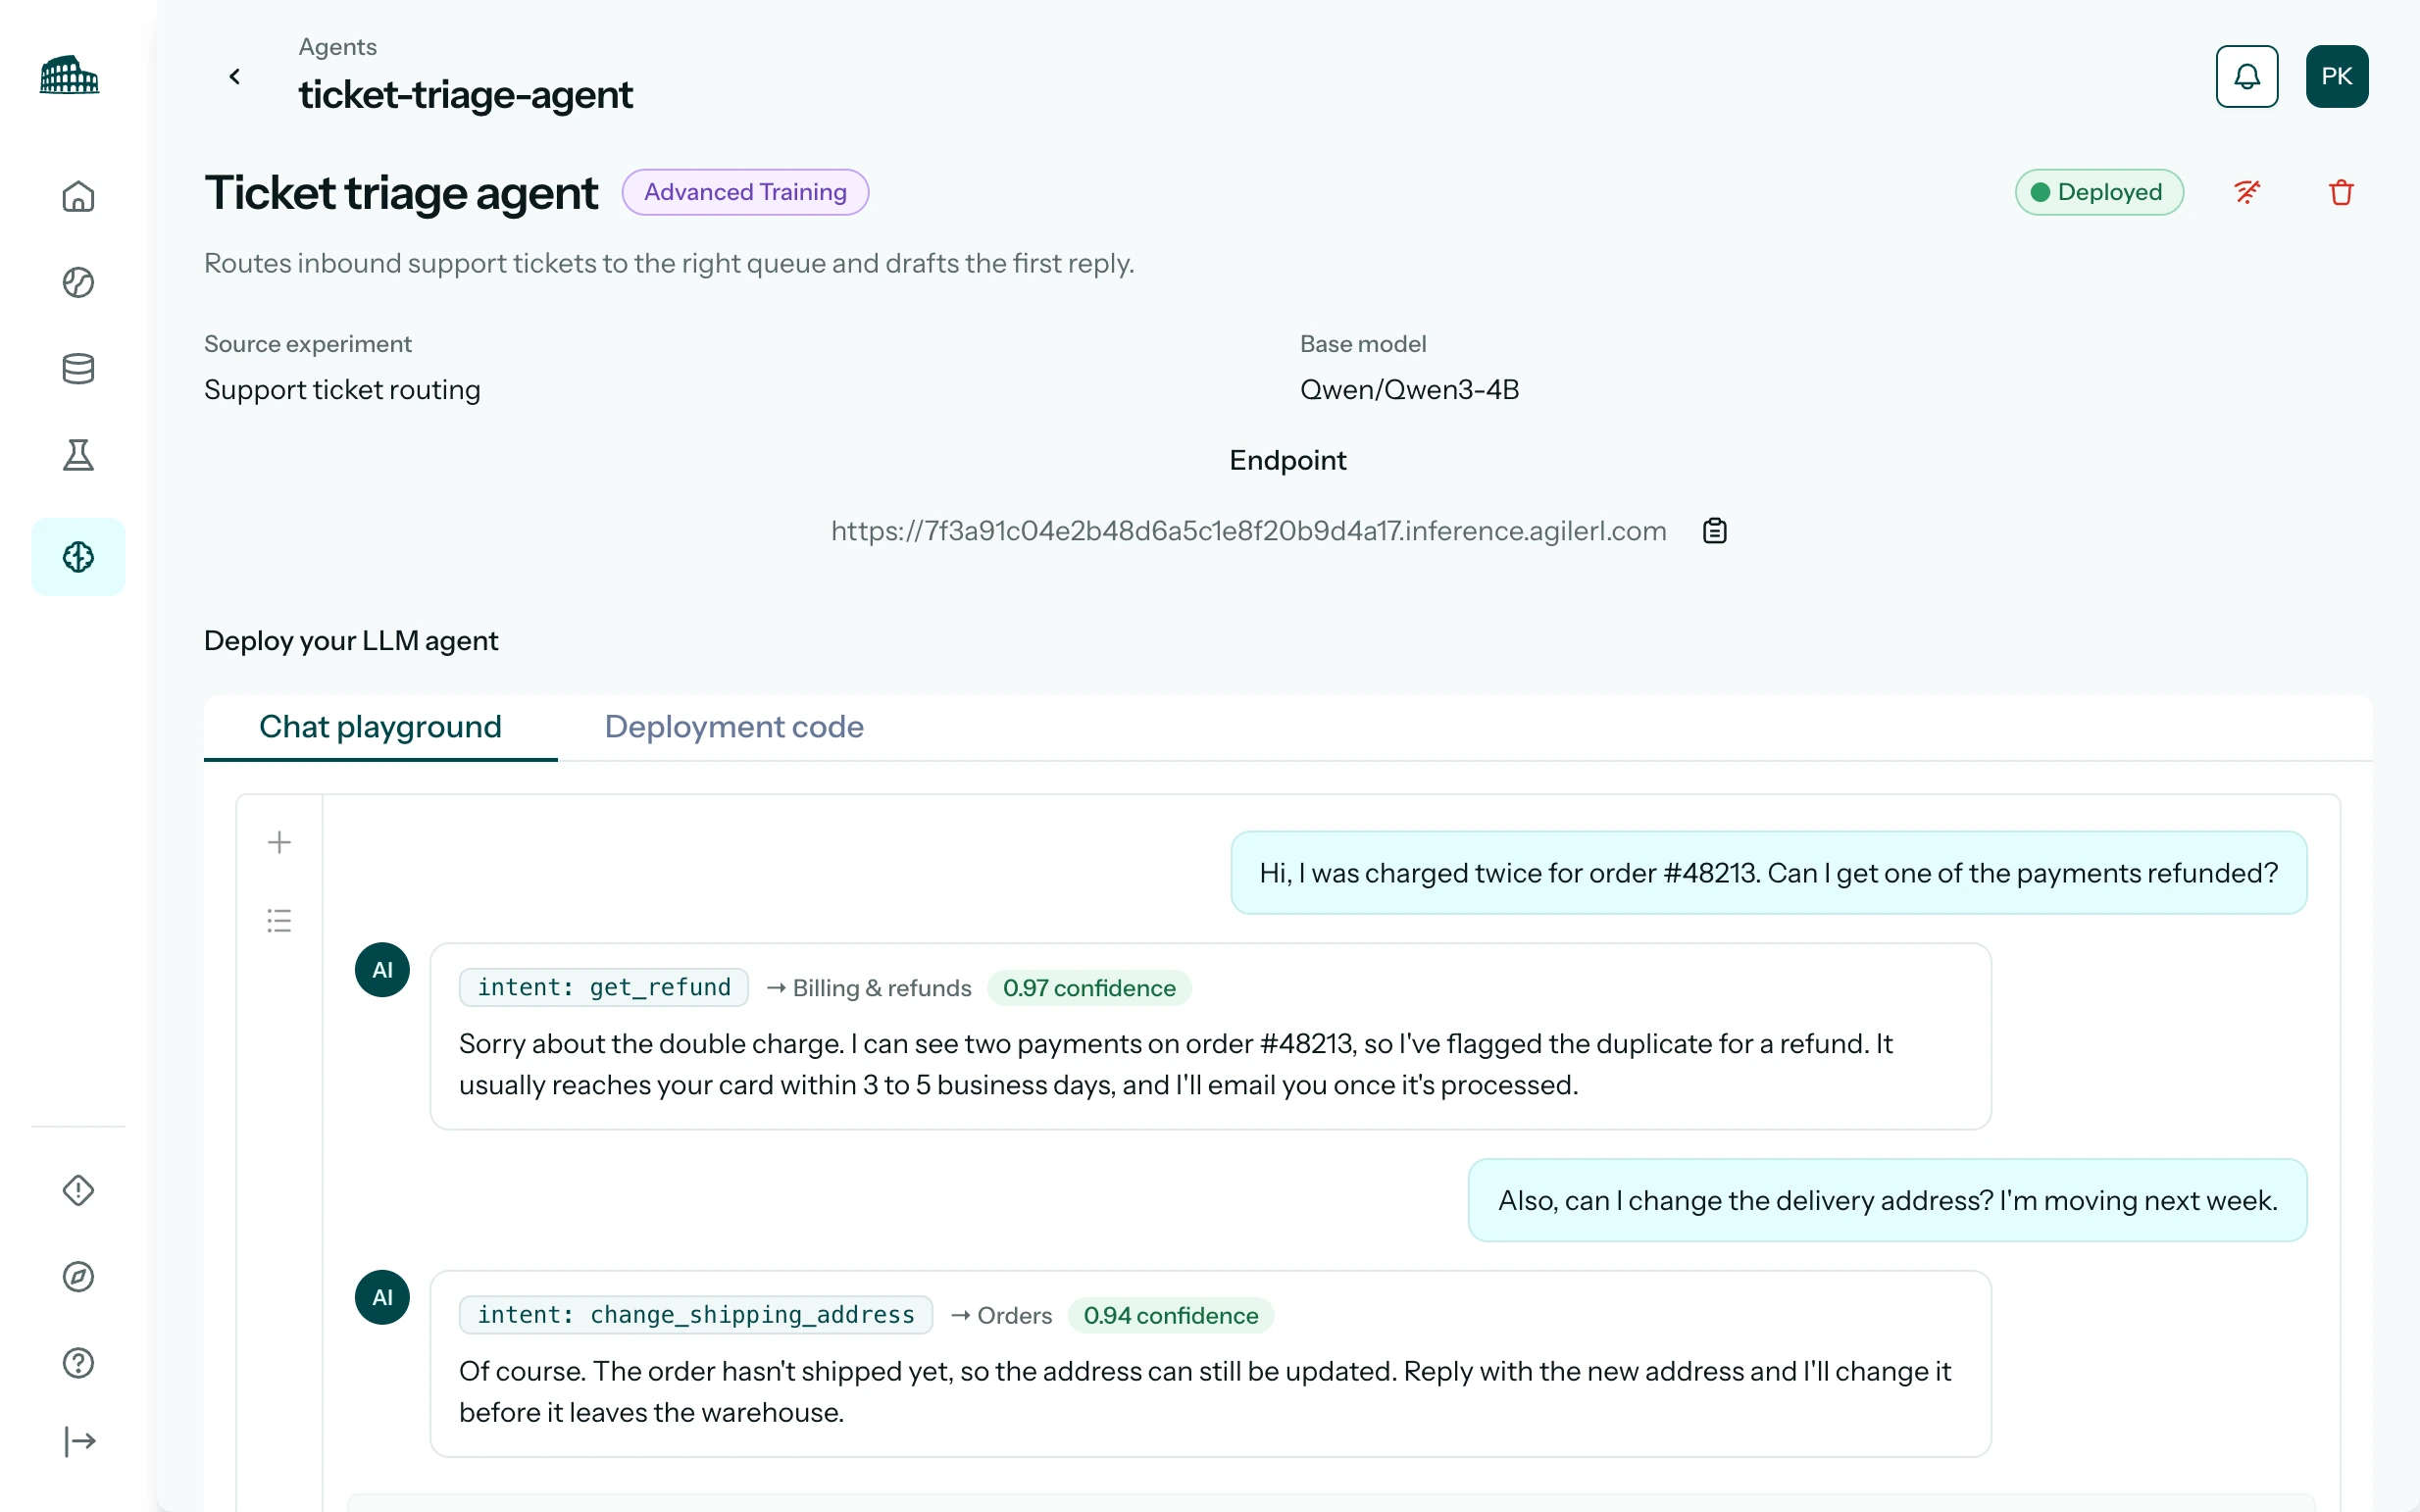
> security
Enterprise teams use Arena because nothing has to leave their perimeter.
Visit the Trust Center →01
Training runs in your environment
Bring your own cloud or use ours. Your datasets stay where they are.
02
The weights are yours
Every model you train belongs to you, and you can serve it on your own infrastructure.
03
SOC 2 Type II and ISO 27001 certified

> import agilerl
AgileRL is the reinforcement learning library under Arena. Evolutionary hyperparameter optimization tunes a whole population while it trains, so you skip the grid search.
Lunar Lander benchmark
10x fasterOpen-source framework with docs, examples, and community support
Single and multi-agent support across on/off-policy, offline RL, bandit and LLM training
Python-first, compatible with your data and environments
Works with your cloud compute and scales to multi-GPU
10x faster
Training with open-source v2

Used by leading research labs and institutions
450,000+
Downloads from the community
10x faster: AgileRL evolutionary HPO vs. a leading hyperparameter optimization library on the Lunar Lander benchmark shown above.
Bring a task, dataset, or environment. We'll train, tune, and deploy an agent on it with you in a live session.
Book a demo